snlp-2
Introduction to deep neural networks
Introduction
In this course, we'll discuss several types of neural networks. We'll begin this journey by examining the simplest form of neural network: the multilayer perceptron (MLP), which is a subtype of feedforward neural networks.
Objectives
- describe the components of a simple feedforward neural network
- convert simple functions to computation graphs
- describe how a neural network learns
Getting started
Before reading further, watch the following video series from Grant Sanderson (3blue1brown)
If you're rusty on matrix multiplication, review one of the following resources:
Background resources
The resources linked below provide helpful background on the topics covered in this lesson:
- OPTIONAL: Sections 1-3 of Yoav Goldberg's Primer on Neural Network Models for NLP
- Section 4 of Yoav Goldberg's Primer on Neural Network Models for NLP
- 7.0 - 7.4 of Jurafsky and Martin's Speech and Language Processing
Moving from one neuron to a neural network
In LING 539, we had an introduction to one possible building block of neural networks, logistic regression, which we can think of as a type of artificial neuron with a particular activation function, the sigmoid. Imagine each circle in the following diagram as a logistic regression:
This is one possible design a mulilayer perceptron (MLP) can take. The MLP depicted above has two hidden layers (layers other than the network's input and output). All neural networks are composed of interconnected neurons, though the particular configuration of these connections and the internal structure of each neuron may differ. All MLPs have some fixed-size input layer and one or more hidden layers each comprised of one or more neurons[^neuronaka]. The layers are arranged sequentially (). As the name suggests, the input layer is the first layer in the network. It provides the initial numerical representation of each datapoint.
Properties universal to MLPs
- at least one hidden layer
- fully connected
- every neuron in one layer of the network is connected to every neuron in the next layer. The output of one neuron becomes part of the input to all neurons in the next layer of the network (each of these inputs takes some learnable weight).
Networks with at least two hidden layers (such as the one shown above) are the shallowest form of deep neural networks.
Defining multilayer perceptron
There is some ambiguity about the definition of a multilayer perceptron (MLP).1 We will take it to mean a fully connected feedforward neural network with neurons exhibiting the following properties:
- each neuron in the network takes as input a) activations from the immediately previous layer, b) weights, and c) a bias term (might be set to zero).
- A linear transformation2 of the form (a matrix multiplication and vector addition) is applied to the input.
- The result is then fed into some activation function that is typically non-linear.
Activation functions
So far we've only discussed the sigmoid, but that's certainly not the only kind of nonlinear activation function. In fact, using the sigmoid can lead to very flat gradients (that's a big problem which we'll cover later).
In later lessons, we'll look at why we might want to use one activation fuction over another. If you're curious about other options, you can interactively compare some commonly used activation functions using Justin Emery's tool:
Classifying with MLPs
Recall that logistic regression is a linear model.
Why is logistic regression linear?
Logistic regression includes no interaction between the feature values (ex. ). Of course, one can alter the input () to include such information (ex. ), but as a model encodes no such trick. No matter the value of or selected, you're going to end up with a dimensional hyperplane.
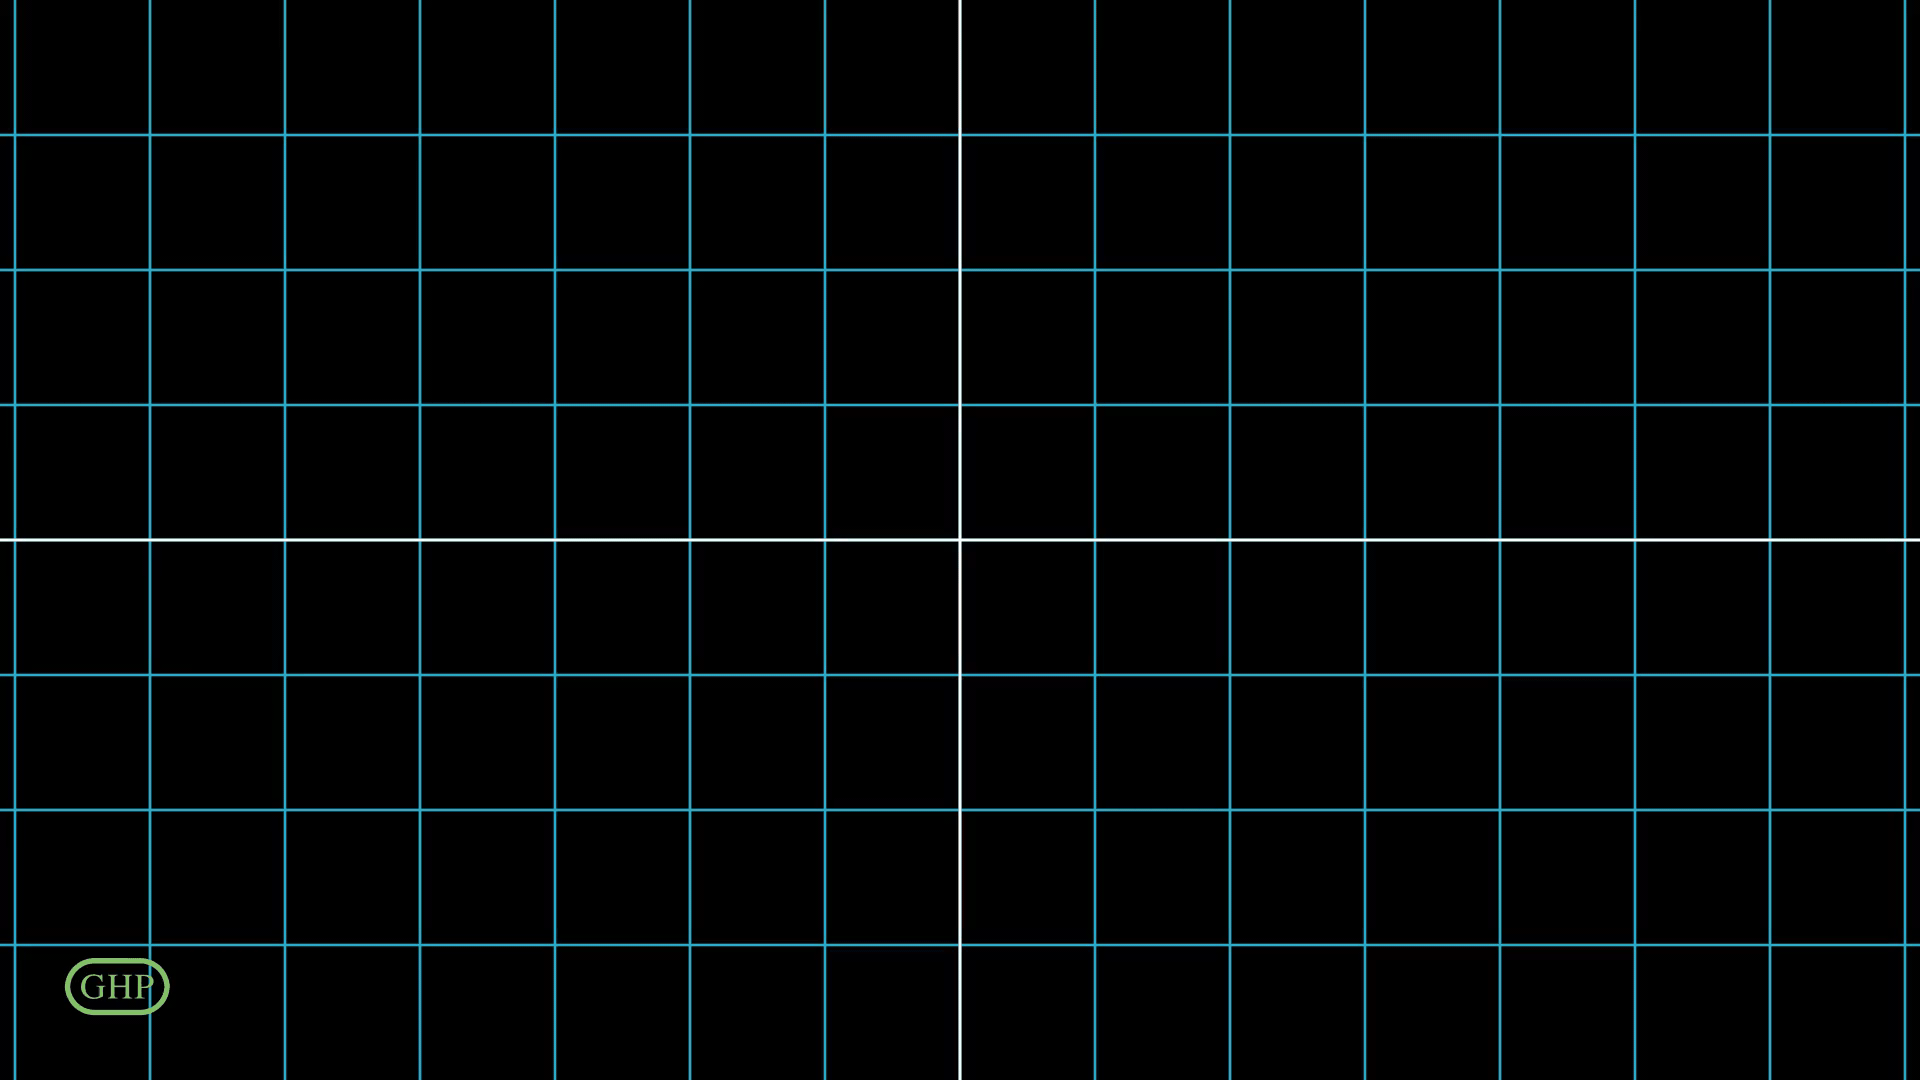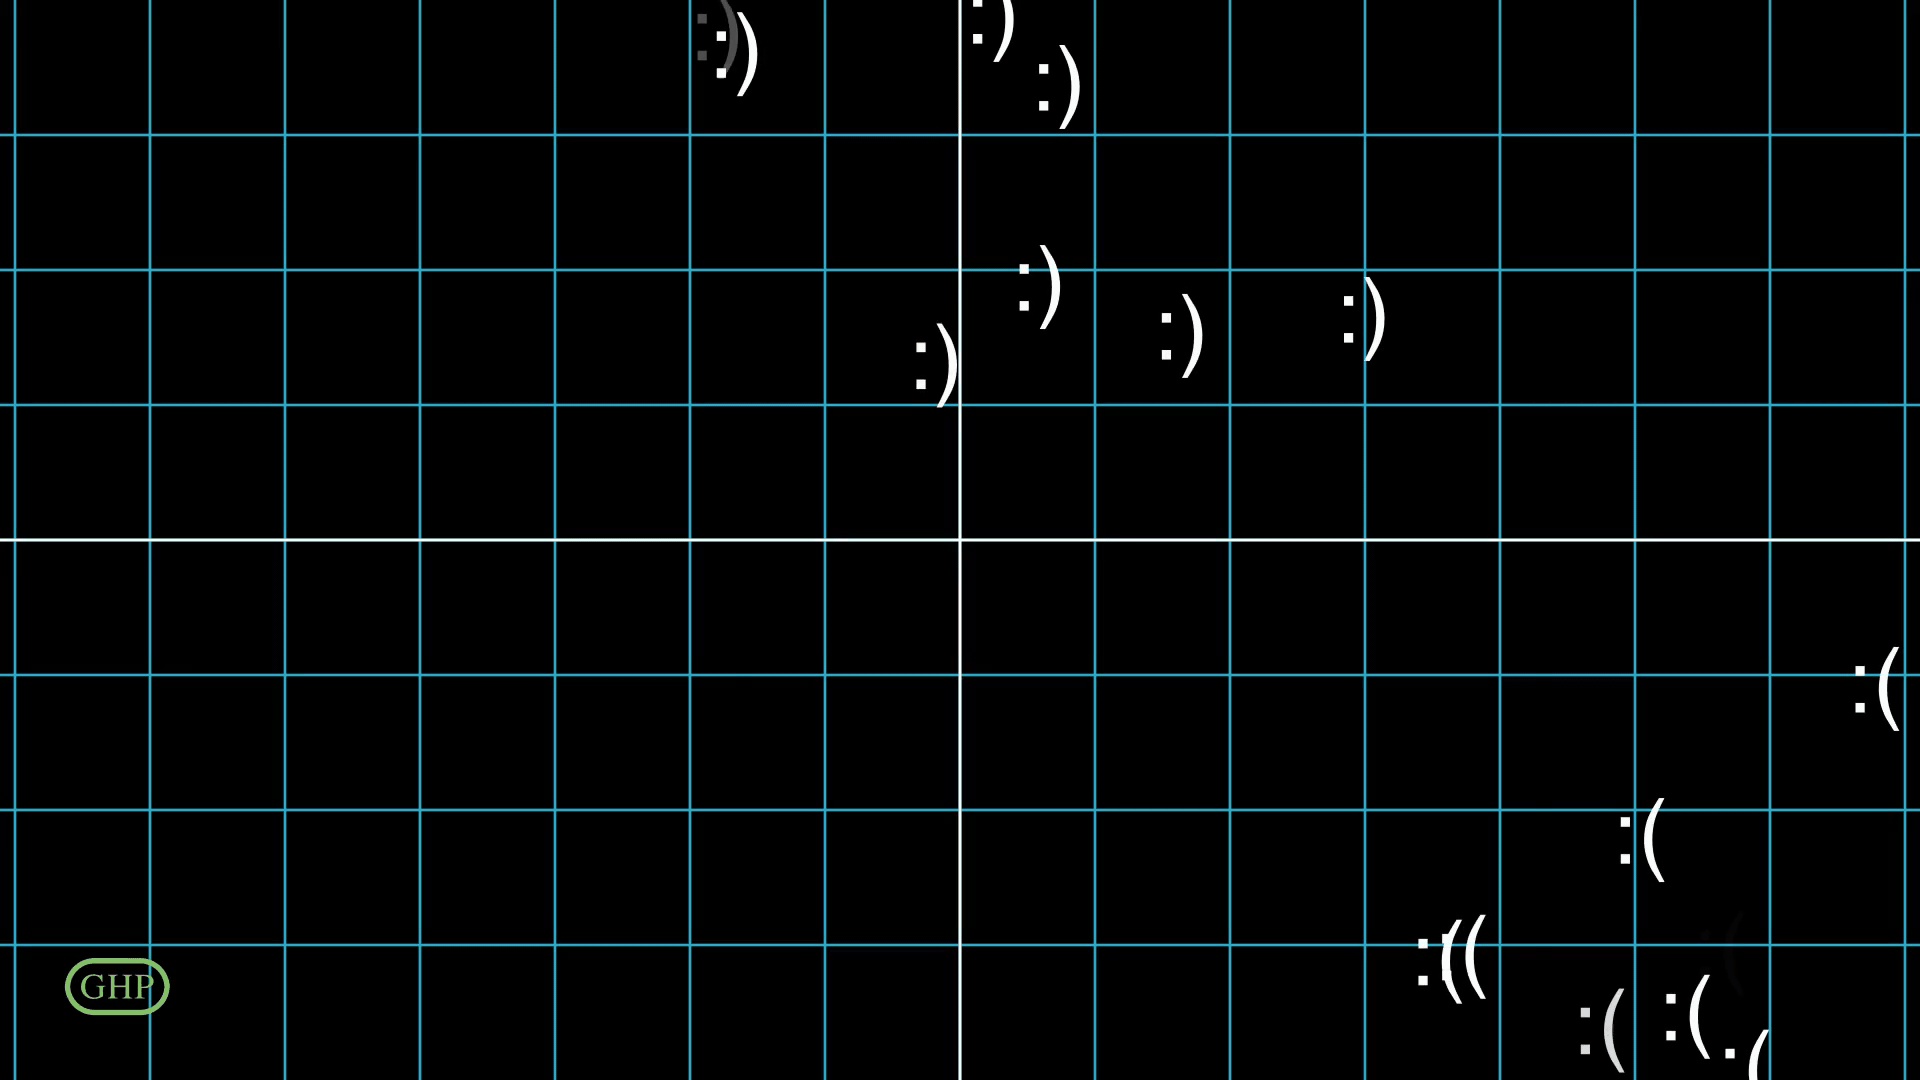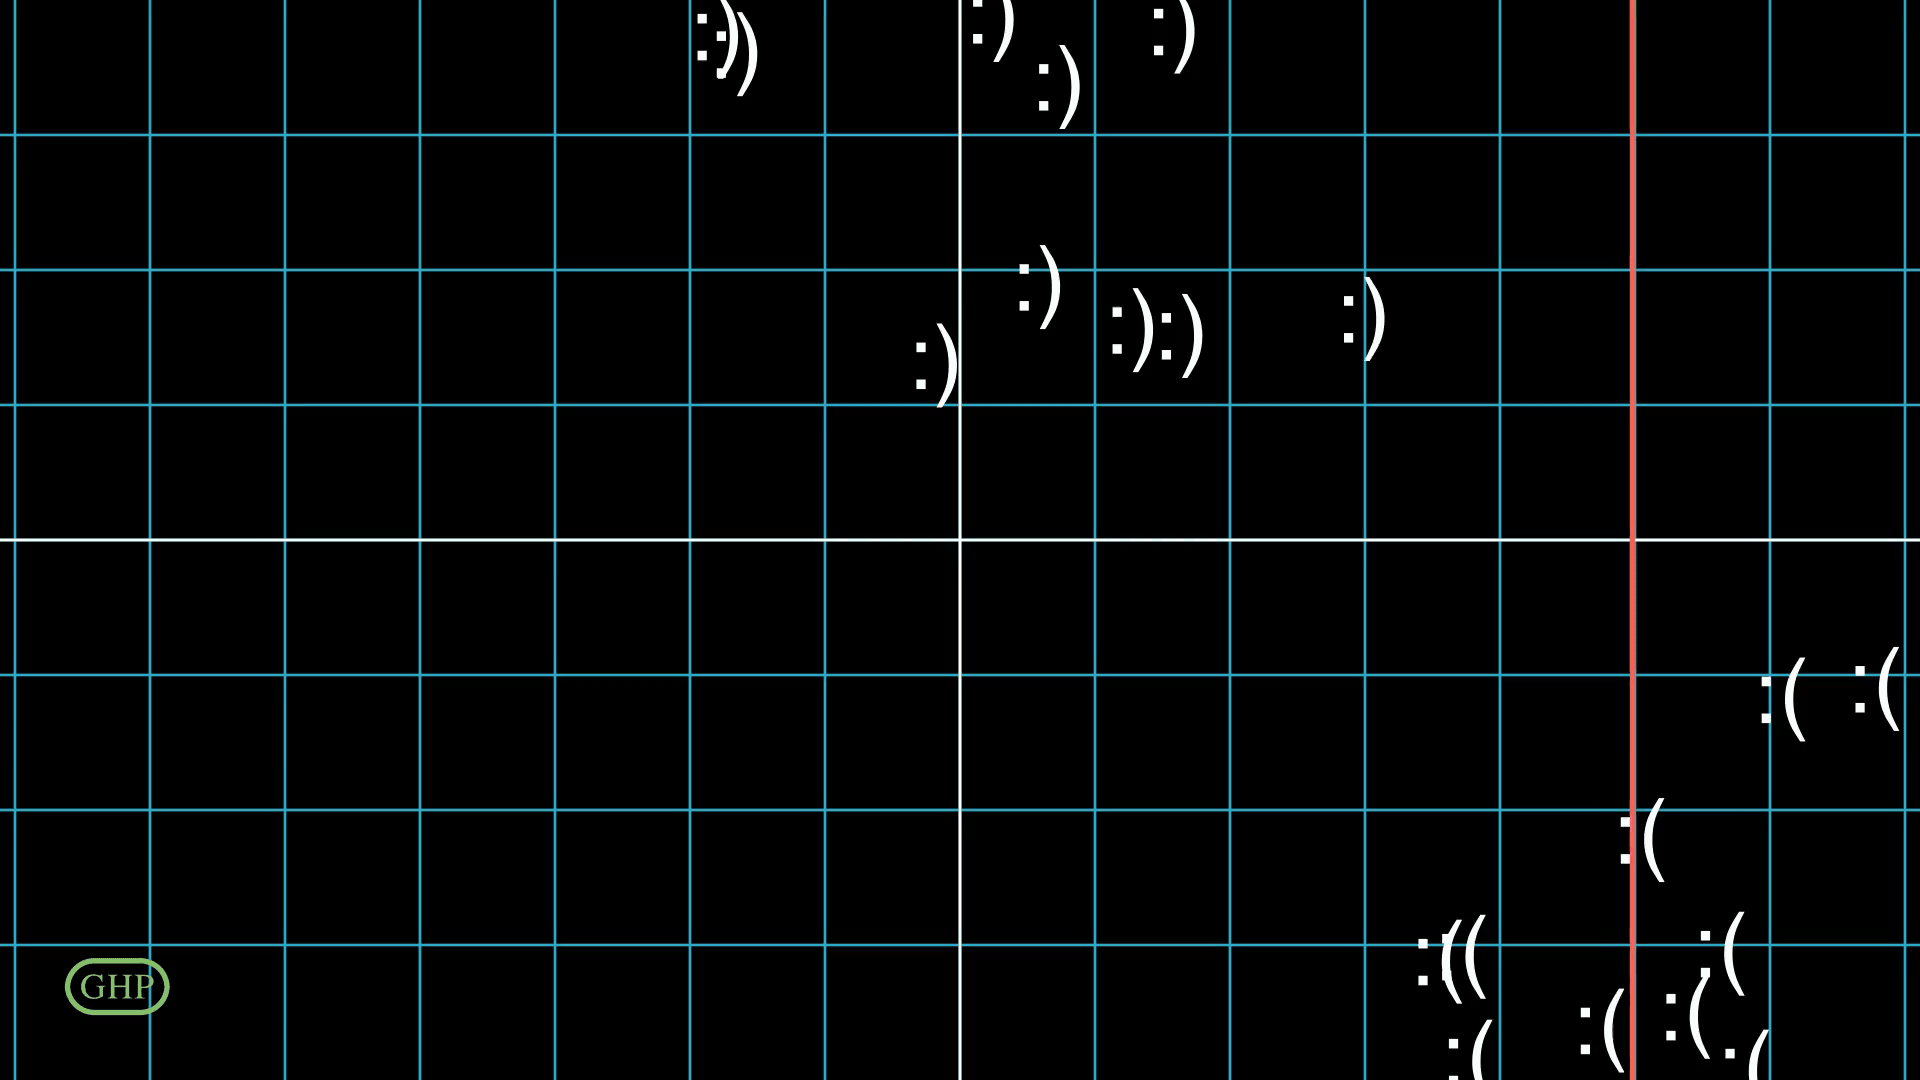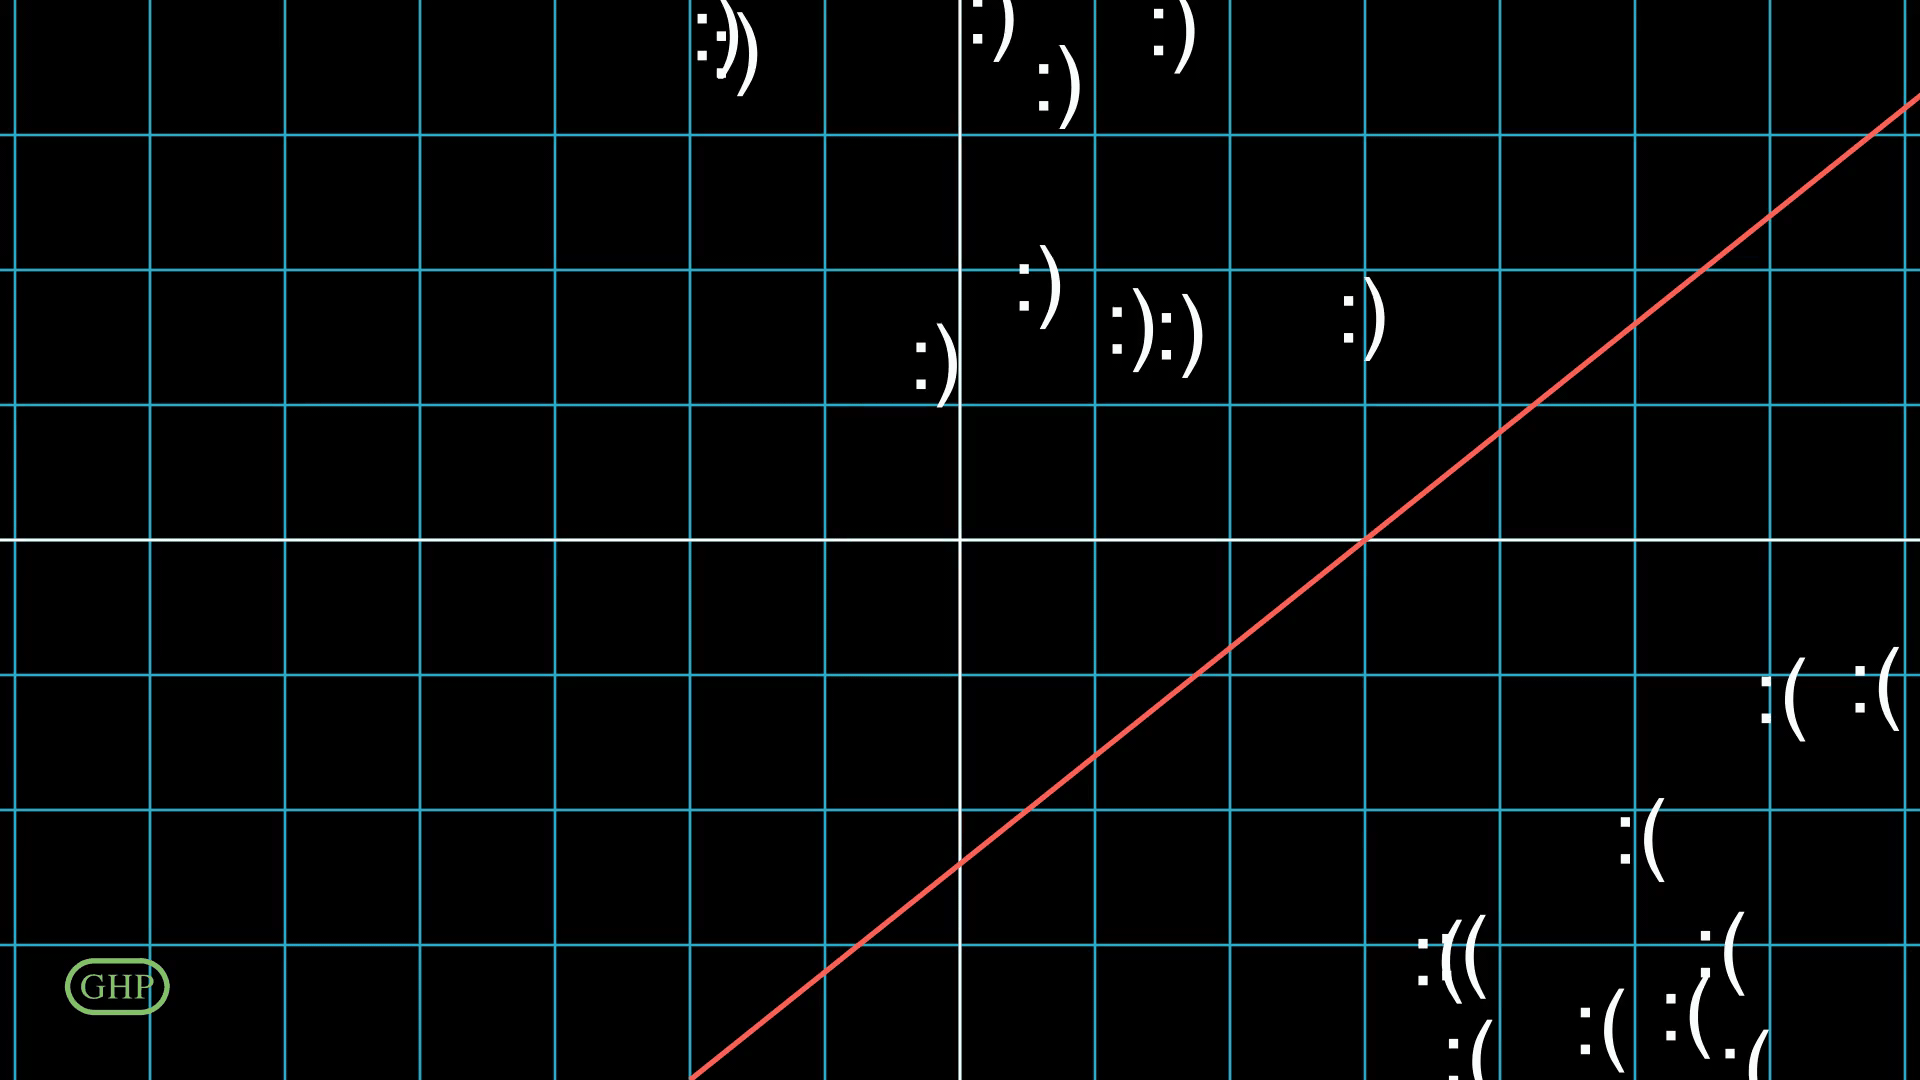
Like logistic regression, an MLP can be used to classify linearly separable data by iteratively updating its parameters to minimize prediction errors:
Beyond linear models
Deep MLPs, however, can learn to classify data that is not linearly separable.
More impressive still, under the right conditions, a neural network is a universal approximator. In other words, given enough data (and sufficiently expressive input), we can use a certain class of neural networks to approximate any function to an arbitrary level of precision [2015].
We've looked at simple neural networks at a high level, but how are these implemented in practice? In this course, we won't reinvent the wheel by implementing neural networks from scratch (though this can be an enlightening exercise!). Instead, we'll design and train our networks using a popular, powerful, and efficient library. Let's look at a couple of key components and features of frameworks like PyTorch.
Learning our parameters
Given some objective, one can imagine many ways you might optimize the parameters of neural network. For example, you might repeatedly try random sets of parameters. Alternatively, you could alter a single parameter in the network slightly and observe its effect on the loss. As you might guess, the problem with such methods is that they are extremely inefficient. These approaches quickly become infeasible as you increase the number of parameters. Deep MLPs can have many parameters (each neuron has weights leading into it), but commonly used models in NLP today have millions (sometime billions and even a trillion) parameters!
Fortunately, there is an efficient method to updating these parameters (and we've already seen a form of it). Just like we saw with logistic regression3, we'll measure our error, compute our derivatives, and use gradient descent to actually update our parameters.
Computation graphs
Frameworks like PyTorch can record the operations we perform as a computation graph. The graph shows how intermediate values depend on earlier values. It also provides a way to work backward from the loss and compute how sensitive that loss is to each of our learnable parameters.
Architecture
Let's return to logistic regression with a single input feature:
Here, is our input, is a weight, and is a bias. All three are scalars. The sigmoid gives us a prediction between 0 and 1. Our model learns and ; for a given example, we keep fixed.
At the level of the architecture, we have one input feeding into one neuron:
Loading diagram
The computation graph opens up that neuron into its individual operations. We can express those operations in a few lines of Python:
import torch

u = w * x
z = u + b
a = torch.sigmoid(z)
loss = loss_fn(a, y)
The names in this code match the names in the graph below. is the target label, and loss_fn compares our prediction with that target. For this example, we'll use binary cross entropy, as in logistic regression.
Forward pass
In the forward pass, we compute our output (a prediction) given some input. When training, we use that output (prediction) to compute our loss†.
Suppose , , and . First, we multiply the input by the weight to get . Adding the bias gives , and applying the sigmoid gives .
The visual below starts with those values and a target of . Change the weight or bias and watch the intermediate values, prediction, and loss. Which values change when you adjust the bias? Which stay the same?
Logistic regression visual
Each operation uses values computed earlier. For example, sigmoid takes as its input; it does not need to know whether came from an addition, a multiplication, or even a more complicated network.
Here's the same dependency structure as a static graph:
Loading diagram
The circular nodes supply the input (), parameters ( and ), and target (). The rectangular nodes perform operations and pass their results along the arrows. Following the arrows lets us answer questions about dependencies. Changing can change , , and the loss, but it cannot change .
Backward pass
Once we've computed the loss, we can work backward through the graph to compute gradients. A gradient tells us how sensitive the loss is to a small change in a value. For a single scalar parameter, think of it as the local rate of change of the loss per unit change in that parameter.
Select Backward in the visual above. It shows the gradient of the loss with respect to each intermediate value and, below the graph, the gradients for and . The red upward arrows indicate the direction of the backward computation. Values computed during the forward pass are still visible.
At the starting settings, the weight gradient is and the bias gradient is . Their negative signs tell us that a small increase in either parameter would reduce the loss here.
This process of computing gradients by working backward is called backpropagation. The graph below highlights the path from the loss to our parameters:
Loading diagram
In this second diagram, the red edge labels identify local derivatives: how one operation's output changes with one of its inputs. These differ from the gradients displayed in the interactive visual, which describe how the final loss changes. We combine the local derivatives along a path to obtain a gradient of the loss.
The idea is basically this:
Loop over the nodes in reverse order starting from the last node in the graph
Use each operation's derivative rule to pass the gradient back to its inputs.
Combine these contributions using the chain rule until we reach the parameters whose gradients we need.
Let's look at what partial derivative each red edge in our example backward graph represents:
You can read as the derivative of wrt4 . In other words, at what rate does change as changes?
Looking at our computation graph, we have a composition of functions. In order to figure out how to update our parameters, we'll compute partial derivatives and use the chain rule from calculus:
For example, affects through . To compute the derivative of with respect to , we combine the rates of change along that path:
If you're beginning to freak out from the sight of derivatives, I've got good news: PyTorch supports automatic differentiation, or autodiff, to handle this for us. The key idea is to follow the dependencies: a change in changes , which changes , which can change the prediction and loss.
From gradients to learning
Computing gradients and updating parameters are separate steps. In PyTorch, loss.backward() computes gradients and accumulates them† in the parameters' .grad attributes. An optimizer then uses those gradients to update the parameters.
For basic gradient descent, we subtract the gradient multiplied by a learning rate†.
The simple curve below illustrates this with a different loss, . Its minimum is at . We start at , where the gradient is . Compare learning rates of , , and .
Learning rate and overshooting
Now return to our logistic regression example. The code below supplies the gradients shown in our computation graph visual at its starting settings. Before running it, predict the updated values of and . Do you expect the loss to increase or decrease?
from math import exp, log

x = 2.0
y = 1.0
w = 0.5
b = -1.0
learning_rate = 0.1

# Gradients computed at these starting settings.
w_gradient = -1.0
b_gradient = -0.5

def loss_for_example(w, b):
    z = w * x + b
    a = 1 / (1 + exp(-z))  # sigmoid
    return -y * log(a) - (1 - y) * log(1 - a)

loss_before = loss_for_example(w, b)
w = w - learning_rate * w_gradient
b = b - learning_rate * b_gradient
loss_after = loss_for_example(w, b)

print(f"Updated parameters: w = {w:.2f}, b = {b:.2f}")
print(f"Loss before: {loss_before:.3f}")
print(f"Loss after: {loss_after:.3f}")
At our starting settings, a learning rate of would change from to and from to . Try those values in the visual with . Does the loss decrease?
Automatic differentiation
In the practice activity for this unit, we estimate a local rate of change by nudging an input and dividing the resulting output change by the input step. This is a finite difference approximation. It gives us a useful way to interpret a derivative.
PyTorch's automatic differentiation, or autodiff, uses a different approach: it records operations and combines their derivative rules using the chain rule. It does not need to repeatedly nudge each parameter and rerun the model to estimate a gradient. Its computed gradients are still subject to the usual limits of floating point arithmetic.
For this lesson, focus on reading the graph, identifying what depends on what, and interpreting what a gradient tells us. PyTorch's introduction to autograd shows how these ideas appear in code.
Further reading
For a deeper look at backpropagation and automatic differentiation, see the following resources:
Next steps
Learn how to implement, train, and evaluate a neural network using PyTorch
Want to play around with deep MLPs? See this interactive tool from Tensorflow
References
- Goldberg, Yoav (2017). Neural Network Methods for Natural Language Processing. Morgan \& Claypool Publishers ebookcentral.proquest.com/lib/uaz/reader.action?docID=4843762
- Jurafsky, Dan and Martin, James (2019). Speech and Language Processing: An Introduction to Natural Language Processing, Computational Linguistics, and Speech Recognition. Pearson Prentice Hall 11--12 public.parsertongue.org/readings/slp3/5.pdf#page=11
- Jürgen Schmidhuber (2015). Deep learning in neural networks: An overview. Neural Networks. 85--117 10.1016/j.neunet.2014.09.003
- Yann LeCun and Yoshua Bengio and Geoffrey Hinton (2015). Deep learning. Nature. Springer Science and Business Media, LLC 436--444 10.1038/nature14539
- Timothy P. Lillicrap and Adam Santoro and Luke Marris and Colin J. Akerman and Geoffrey Hinton (2020). Backpropagation and the brain. Nature Reviews Neuroscience. Springer Science and Business Media LLC 335--346 10.1038/s41583-020-0277-3
- Geoffrey Hinton (2013). Where Do Features Come From?. Cognitive Science. Wiley 1078--1101 10.1111/cogs.12049
- Nielsen, Michael A. (2015). Neural Networks and Deep Learning. Determination Press neuralnetworksanddeeplearning.com
- David E. Rumelhart and Geoffrey E. Hinton and Ronald J. Williams (1986). Learning representations by back-propagating errors. Nature. Springer Science and Business Media LLC 533--536 10.1038/323533a0
Footnotes
- the precursor to the MLP is the Perceptron algorithm (the P in MLP) which served as the neurons of the MLP. Rather than assume the same activation function as the Perceptron, here we take a general view of a neuron by assuming it can take any activation function. ↩
- If you're unclear on what makes this transformation linear, have a look at this resource. ↩
- In LING 539, we talked about minimizing our loss using gradient descent to iteratively update our parameters. As a refresher, Section 5.4.3 of [2019] provides a walkthrough example. ↩
- with respect to ↩